Compare Machine Utilization Across Shifts
Compare Machine Utilization Across Shifts (Without Chasing the Wrong Fix)
If Shift 1 “always looks fine” and Shift 2 “always struggles,” a blended weekly utilization number will rarely tell you why. It smooths out the losses, turns real operational patterns into averages, and pushes leaders toward expensive or distracting fixes—more machines, more overtime, another scheduling reshuffle—before they’ve recovered the capacity already sitting in the gaps between shifts.
Comparing utilization across shifts isn’t about judging people. It’s a diagnostic method: when the same machines run differently on different shifts, the delta usually points to a specific constraint—training and prove-out discipline, staffing mix, tool/staging readiness, handoffs, or dispatch decisions.
TL;DR — Compare machine utilization across shifts
Use identical definitions, time windows, and shift boundaries—or the comparison is noise.
Separate scheduled losses (breaks, planned maintenance) from unscheduled losses before blaming a shift.
Compare components (Run, Setup, Waiting/Blocked, Down/Fault), not just a single utilization %.
Add “start-of-shift ramp” and “post-break recovery” to expose repeatable leakage.
High utilization can still miss ship dates if the shift runs the wrong mix (dispatch/handoff issue).
ERP timestamps are too coarse for intra-shift diagnosis; controller signals reduce bias and lag.
Start small (5–10 machines), lock rules, and review deltas daily for 2 weeks to find the real constraint.
Key takeaway A shift-to-shift utilization comparison only becomes actionable when it’s truly comparable: the same definitions, the same capture method, and the same boundaries. Once it is, the delta usually reveals where capacity is leaking—setup/prove-out drift, waiting on inputs, or dispatch and handoff decisions—so you can correct behavior and readiness during the week instead of buying capacity you already have.
Why a single utilization number hides the real constraint
A blended utilization number can look stable while one shift quietly bleeds capacity every night or weekend. When you average three shifts together, the “good” shift masks the “leaky” one, and the weekly report reads like a steady state problem instead of a specific, fixable pattern.
Shift deltas are often controllable. A gap between Shift 1 and Shift 2 can indicate staffing mix, supervision coverage, job readiness, tool control, or breakdowns in the handoff between scheduling/programming and the floor. Those causes rarely show up in ERP completion times until days later—if at all—because ERP tends to reflect what was supposed to happen, not how the machines behaved by the hour.
What leaders can’t see in an average is when losses occur: the first 10–30 minutes of a shift, the re-start after breaks, the last hour cleanup, or the “waiting for first article approval” period that repeats every evening. When you segment by shift, those patterns stop hiding.
The decision enabled by shift comparison is simple: what (or who) should you fix this week to recover capacity before you add machines or add headcount. This is a subset of the broader discipline covered in machine utilization tracking software, but the emphasis here is on isolating the shift-level constraint quickly enough to act during the same week.
Set up an apples-to-apples comparison (definitions and boundaries)
“Compare across shifts” only works if every shift is measured with the same yardstick. Before you interpret any delta, lock down the boundaries and rules that make the data comparable.
Start by fixing shift boundaries, break handling, and overtime attribution. If overtime bleeds past the shift end, decide which shift “owns” it—and keep that rule consistent. A common failure mode is letting supervisors record breaks differently, which makes one shift look worse simply because they were more honest.
Next, separate scheduled time from unscheduled time. Planned maintenance, scheduled meetings, and approved training blocks shouldn’t be treated as utilization losses for that shift. If you don’t separate them, you’ll punish the shift that had planned work and reward the shift that deferred it.
Keep machine states minimal but consistent: Run/Cycle, Idle/Waiting, Setup, Down/Fault. Don’t let each shift invent their own categories. The guardrail is strict: if definitions change by shift, you’re not comparing performance—you’re comparing vocabulary.
Finally, normalize for planned staffing differences. If Shift 3 runs a skeleton crew and is expected to do fewer changeovers, don’t compare it to Shift 1’s peak-coverage window. Compare like-for-like windows (e.g., “first 6 hours after handoff” across all shifts) so the delta points to process and readiness—not the org chart.
What to compare: utilization components that point to training vs staffing vs inputs
A single utilization percentage tells you magnitude. The components tell you the type of problem. For shift comparisons, break utilization into a small set of diagnostic slices that lead to fast hypotheses.
Compare, at minimum: Run time %, Setup/Changeover %, Waiting/Blocked %, and Down/Fault %. When Setup is higher on one shift, it often points to variance in standard work, prove-out discipline, tool availability, or program readiness. That is not “operator speed”; it’s frequently a readiness and method problem.
When Waiting/Blocked is higher, look upstream: material not staged, inspection delays, missing travelers, late program release, or tooling that wasn’t pre-set. This is where manual reporting can mislead you—operators log “waiting” differently depending on the shift culture. If you’re still relying heavily on paper notes, it’s worth understanding the limits of manual operations tracking before you try to manage shift deltas from it.
Down/Fault time is its own slice: the goal is not predictive maintenance narratives, but response-time clarity. If Shift 2 has more “down,” is it because the machines fail more, or because maintenance response and restart procedures differ by shift?
Two sub-metrics are especially revealing: start-of-shift ramp time (how long until first stable cycle) and post-break recovery (how quickly machines return to cutting). These are repeatable patterns you can correct with staging, handoff rules, and clear ownership—often without any capital spend.
Real shop-floor patterns: interpreting common shift deltas (without blaming operators)
Shift deltas are valuable because they narrow the search space. The same machine, same part family, different shift outcome—something about readiness, decisions, or methods changed.
Lower utilization + higher setup
Check setup sheets and revision control, tool availability/pre-set process, prove-out policy (who is allowed to tweak programs), and first-article flow. If the shift is re-proving out what another shift already proved, that’s a handoff and standardization gap. Validate with a 15-minute gemba during a changeover: are they searching for holders, waiting for offsets, or re-reading prints because the traveler is unclear?
Lower utilization + higher idle/waiting
This usually points to dispatching, staging, shortages, inspection queues, or late engineering releases. Confirm what the machines were waiting on, not just that they were waiting. A quick check is to compare “waiting” blocks against schedule changes or material pulls: if the idle windows start right after a job completes, the next job wasn’t ready at the handoff.
Higher utilization but worse delivery
This is the trap that gets missed if you treat utilization like the only KPI. A shift can keep spindles turning by running “easy” work or the wrong mix, while priority jobs age in queue. That’s not machine performance; it’s queue discipline, job mix, and handoff. If your shift comparison shows this pattern, you’re looking at decision-making and priority setting, not “work ethic.”
Big variance by day of week
If Fridays or weekends dip, look for training coverage, supervisor presence, changeover clustering, and weekend readiness (are programs/material/tooling staged before the handoff?). These are governance issues, not mysteries.
A practical validation routine is: 15-minute gemba on the constraint area, a machine-state timeline view for one representative machine, and the top 3 loss reasons by shift. If you’re categorizing downtime, keep the scheme consistent; the goal is decision speed. For more on getting loss visibility without turning it into a taxonomy project, see machine downtime tracking.
Scenario walkthroughs: the same weekly utilization, two very different realities
The point of shift comparison is that two shops (or two departments) can report the same weekly utilization and still have completely different constraints. The examples below use illustrative numbers to show how the decisions change once you segment by shift.
Scenario 1: 3-shift CNC milling cell (Shift 2 setup/prove-out drift)
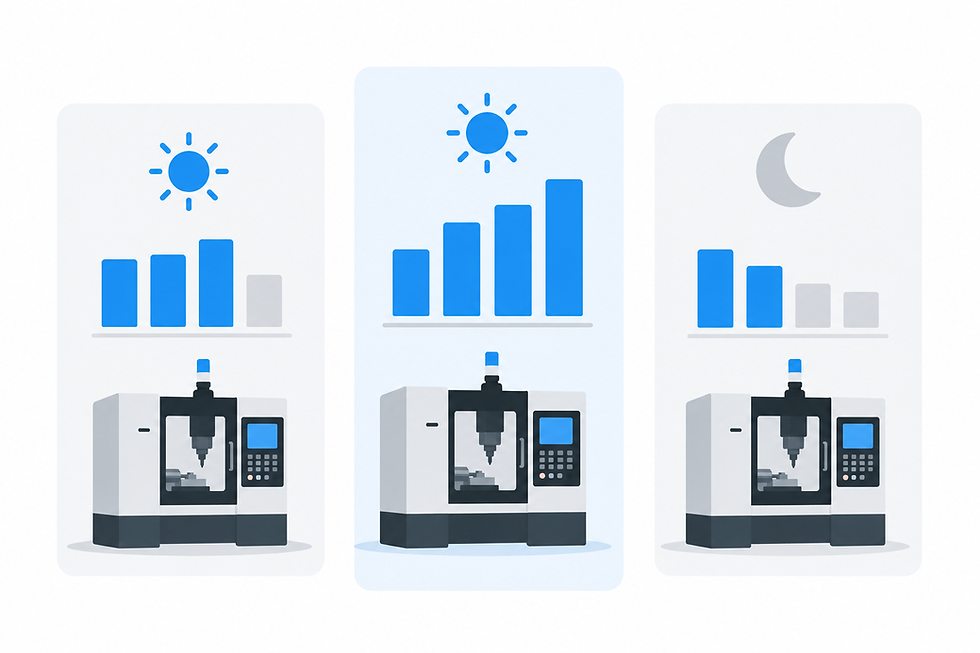
Context: a 3-shift milling cell running a repeat mix of aluminum and steel jobs. The weekly blended utilization reads as “about 65%,” which looks acceptable in a weekly dashboard. But the shift breakdown shows Shift 2 at roughly 52%, driven by longer prove-outs and setup drift—especially after the first break and during handoff from Shift 1.
Illustrative View | Shift 1 | Shift 2 | Shift 3 |
Run (Cycle) | Higher | Lower | Middle |
Setup/Changeover | Lower | Higher | Middle |
Waiting/Blocked | Middle | Middle | Middle |
Top loss theme | Normal variation | Prove-out + setup drift | Handoff readiness |
Likely causes: inconsistent setup method, missing pre-staged tools, program revisions being discovered mid-shift, or a prove-out policy that forces Shift 2 to “re-verify” what Shift 1 already stabilized. The countermeasure is not “push harder”; it’s standardizing prove-out, staging tools and fixtures before handoff, and targeted training for the specific setup steps that are stretching.
Next 3 checks (next shift): (1) audit 2–3 recent setups for missing tools/holders and unclear setup sheets, (2) verify whether program release timing forces edits during Shift 2, (3) observe post-break restart to see if offsets, first-article approvals, or tool touch-offs are causing repeated delay.
Scenario 2: Lathe department (Shift 3 runs hard, ships late)
Context: a lathe department with a strong night shift. The utilization component view shows Shift 3 with high run time (illustratively, “around 75% run”), yet parts-to-go on hot jobs barely move and ship dates are missed. The shift looks “efficient,” but the constraint is dispatching and priorities: Shift 3 is running the wrong mix because the handoff is unclear, travelers are inaccurate, or the queue isn’t aligned to due dates and bottlenecks.
Likely causes: priority list not updated at handoff, kitting incomplete for the true priorities, or Shift 3 choosing long, stable runs to avoid changeovers (which keeps utilization high while delivery performance drops). The fix lives in dispatch rules, kitting/staging discipline, and a tighter handoff—rather than any change to the machines.
Next 3 checks (next shift): (1) compare what Shift 3 ran vs the day shift priority list and bottleneck plan, (2) spot-check travelers for correct revision, quantities, and next-op clarity, (3) confirm whether missing kits/materials drove “safe” job choices that weren’t actually the constraint’s best use.
Mid-article diagnostic filter: if your shift comparison shows “setup-heavy losses,” focus on standard work and readiness; if it shows “high run but wrong outcomes,” focus on dispatch and handoff. Don’t change everything at once—pick one leakage theme and prove it shift-by-shift.
How to capture shift-level utilization you can trust (and what breaks comparisons)
Shift comparisons only work if the data is trusted and timely enough to act on during the same day. In evaluation mode, the key questions aren’t “what dashboards exist?” but: do I trust the capture method, how quickly do I see it, and can I make the same decision across all shifts using the same rules?
Controller/MDC signals typically reduce bias and time lag because they’re driven by machine state rather than recollection. Manual logs drift by shift and supervisor—one shift records every stop, another records nothing until end-of-shift, and a third backfills to match what they think management wants to see. If you’re evaluating options, this is the practical difference between “weekly reporting” and “same-shift correction.” A broader overview of data-capture approaches is covered in machine monitoring systems.
ERP/router timestamps are usually too coarse for intra-shift diagnosis. They’re useful for accounting and quoting feedback, but weak for finding the “leakage” that happens in 10–30 minute chunks—especially around handoffs and breaks.
What breaks comparisons most often: inconsistent downtime codes by shift, missing break logic, rework being hidden as normal run time, and “ghost running” states where a machine is powered but not producing. Another quiet killer is changing definitions midstream—leaders lose confidence because last week’s number is not comparable to this week’s.
A minimum viable rollout is straightforward: start with 5–10 machines, lock definitions, and review shift deltas daily for 2 weeks. The requirement is decision speed—same-shift visibility beats end-of-week reports when you’re correcting dispatch behavior, staging discipline, or prove-out drift.
As you scale beyond a handful of machines, interpretation becomes the bottleneck. Tools that help managers turn raw states into “what should we check next?” can reduce that burden; for an example of assistive analysis, see the AI Production Assistant.
Turn shift comparisons into action: a weekly operating cadence
Shift segmentation only matters if it changes the week. The lightest effective cadence is one that drives fast countermeasures without creating a reporting bureaucracy.
Daily: review yesterday’s shift delta and pick one representative machine history in each constraint area (for example, the milling cell constraint, the lathe constraint, and one shared resource like inspection). The goal is to pinpoint whether the loss was setup drift, waiting on inputs, or down/fault recovery time.
Weekly: choose 1–2 leakage themes and assign an owner with a specific countermeasure (staging checklist, prove-out handoff rule, kitting cut-off time, revised dispatch list). Use “before/after by shift” as proof that the change worked; avoid vanity KPIs that move because definitions changed.
Set escalation rules so shift leaders aren’t blamed for upstream problems. If the pattern is “waiting/blocked,” that may be scheduling, material flow, programming release timing, or inspection capacity—not floor execution. Shift comparison helps you route the problem to the right owner quickly.
Sustainment depends on stability: keep definitions steady and only refine categories or rules with documented change control. Otherwise, trust collapses and the team reverts to anecdotes.
If you’re evaluating implementation, treat cost as a fit question (mixed fleet coverage, install friction, support responsiveness, and how quickly your team can start making same-shift decisions) rather than a spreadsheet exercise with made-up savings. For rollout expectations and packaging context, review pricing.
When you’re ready to validate shift-level comparability on your own machines—using your shift boundaries, your breaks, and your real job mix—the next step is a diagnostic walkthrough. You can schedule a demo and focus the conversation on one constraint area, one week of shift deltas, and what you’d check first.